Orpheus TTS Quantized
Project Overview
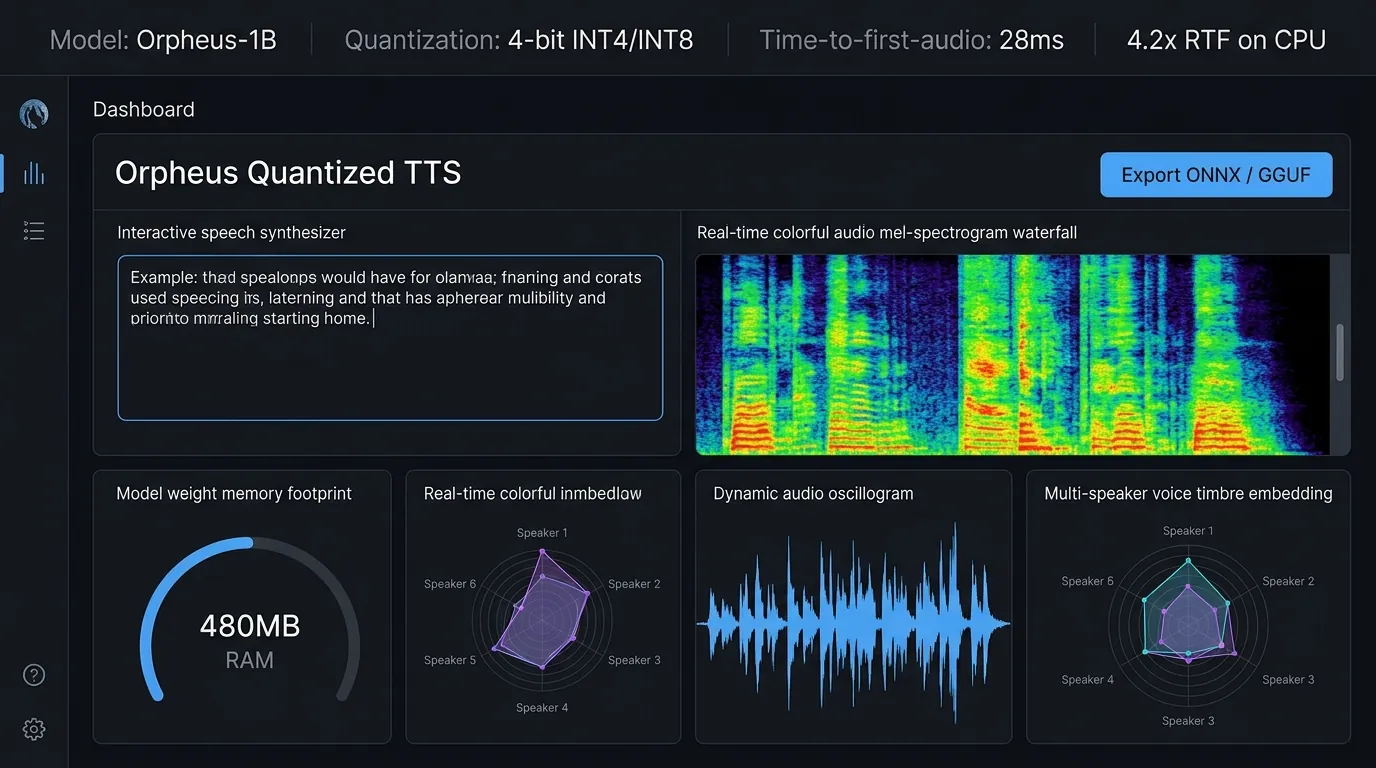
An optimized, resource-efficient implementation of the Orpheus Text-to-Speech model designed for fast local inference.
The Challenge
Running high-fidelity TTS models locally usually requires expensive GPU hardware.
The Solution
Quantized the model weights to significantly reduce memory footprint without severely impacting audio quality.
Client Rating
4.9
Key Results
Enabled local voice generation on standard laptops.
Drastically reduced inference times.
Technology & Skills
PythonMachine LearningTTS